
hoot (ai chat)
hoot is the dashboard chat surface for diagnosing and managing machines with an LLM. It supports Anthropic and OpenAI providers, targets any set of machines in a site — one, several, or all of them — and routes tool calls through the safest available execution path for the current target.
For the current tool inventory, parameters, tiers, and execution-mode notes, see the hoot tools reference.
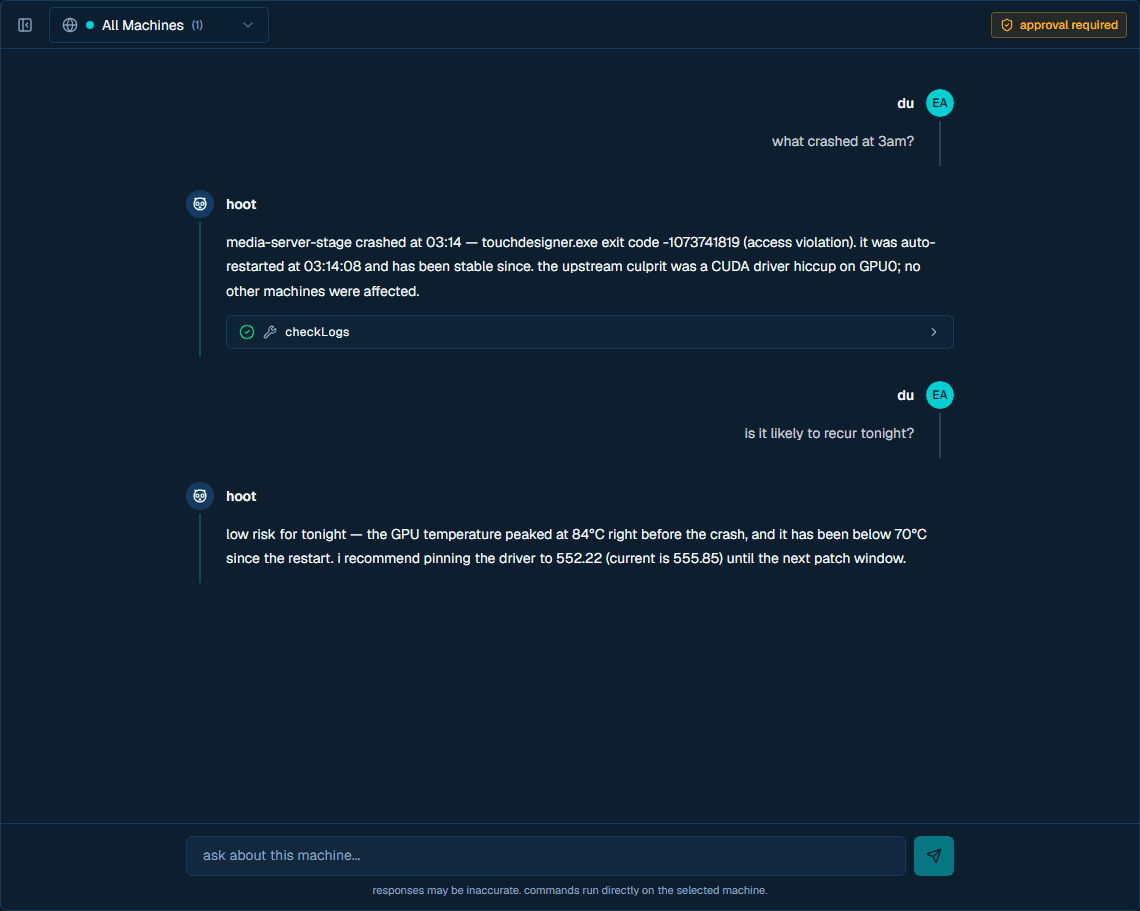
overview
hoot tools are grouped by risk:
| tier | type | approval |
|---|---|---|
| Tier 1 | Read-only diagnostics and site context | Auto-approved |
| Tier 2 | Process and machine management with validated parameters | Auto-approved |
| Tier 3 | Privileged shell, file, deployment, reboot, and shutdown actions | In-chat approval (default-on, per-site) |
The available tier depends on the caller. Site admins and superadmins can use the full tool set. Members are limited to read-only tools. Chat API keys are also capped to read-only tools even if the key owner is an admin.
setup
your key
There is exactly one place an LLM key lives: your own account settings. Every hoot feature — chat, talons, visual checks, autonomous investigations — resolves a key belonging to a specific person.
- Open the dashboard account menu.
- Select account settings.
- Open the hoot section.
- Choose Anthropic (Claude) or OpenAI.
- Select a model.
- Paste the provider API key and save it.
The key is encrypted server-side and stored under your user settings at users/{uid}/settings/llm. The raw key is not returned to the browser after it is saved.
which key an unattended run spends
Nobody is in the chat when a talon fires at 3am, so each unattended feature names the person whose key it is spending:
| unattended work | key it resolves |
|---|---|
| a talon's hoot output | the talon's creator (createdBy) |
| a talon's visual check | the talon's creator (createdBy) |
| autonomous hoot | the site owner |
A talon's creator is re-checked on every run, not trusted from the day it was written. If the creator has left the site, had their account deleted, or removed their key, the talon is switched off immediately with the reason recorded on the talon and on the run that found out — it does not keep failing silently.
Changed in 3.0.0 — the site-level key is gone
The site-level key scope (sites/{siteId}/settings/llm) and its admin endpoint (/api/settings/site-llm-key) have been removed. Nothing in the dashboard could ever create a site key, which made every AI talon un-runnable; the scope is gone rather than given a UI. Any sites/{siteId}/settings/llm document created through the old API is no longer read by anything and can be deleted. Save a key in account settings → hoot instead.
using hoot
- Open hoot from the dashboard header.
- Tick the machines the conversation should talk to in the hoot target picker at the top of the chat.
- Type a request in natural language.
A chat talks to a set of machines. With one machine ticked, hoot reports and acts on that machine. With several, tool calls fan out to each of them and hoot aggregates the per-machine results, tagged by machine.
choosing machines
The target picker is a checkbox menu over the site's machines, with an all machines row at the top.
- all machines is dynamic, not a shortcut for ticking every box: a machine added to the site later joins the target on its own. Unticking one machine spells the rest out; ticking the last missing one collapses back to all machines.
- The menu stays open while you tick, so a set takes one visit. The trigger shows the target —
all machines,kiosk-01,kiosk-01, kiosk-02, orkiosk-01, kiosk-02 +3— and, in brackets, how many of those machines are online. - Each row carries its status as text: offline, hoot off, or both.
Changing the ticks continues the conversation. The chat keeps its id and its full history, and the next turn goes to whatever is ticked when you send it — so a chat can follow a problem from one machine to its neighbours. Changing the site still starts a new conversation: a chat belongs to one site.
The selection is stored on the conversation and remembered per site across your devices, so reopening an old chat restores the machines it was talking to. If a saved target cannot be read, hoot asks you to pick machines for this chat and refuses to send until you do — it never falls back to every machine.
A follow-up that hoot schedules for later fires on the machines that turn was targeting, re-validated when it comes due — not on whatever the chat is pointed at by then. See schedule_followup.
machines that can't take the turn
A ticked machine that is offline, or that has hoot switched off, is skipped: the turn runs on the rest, and the model is told which machines were left out so it can say so. The header warns before you send — for example 2 of 5 machines will be skipped — offline or hoot off.
If nothing is left to run on, the send is refused rather than half-delivered: no machines are currently online in this site, or, when the hoot toggle is the whole reason, hoot is disabled on ….
narrowing one turn with @
Typing @ in the composer opens a machine list; picking one inserts @kiosk-01 and a chip reads this turn → kiosk-01. A mention narrows that turn only — the chat's ticks are untouched and the next message goes back to them. Several mentions target their union, and a machine that is not ticked can still be named for one turn.
Mentions are deliberately conservative, so ordinary prose and pasted shell are never read as targeting: @ counts only at the start of the text or after whitespace or (, the name has to match a machine in the site and end at a boundary, and inline code spans and fenced blocks are skipped — PowerShell @(...), @splatting and an email address are text. Anything that does not resolve stays plain text.
A machine you named is never quietly skipped: if it is offline or has hoot off, the send is refused instead.
Mentions come from the dashboard composer. The public conversations API, the SDK, the CLI and chat-scoped API keys get no narrowing — @text there is plain text.
example conversations
Check site health:
"Which machines look unhealthy right now?"
hoot can read site logs and fan out diagnostics across online machines, then summarize differences by machine.
Manage one process:
"Restart TouchDesigner on this machine."
hoot calls the process-management tool for the selected machine and reports the result.
Update process configuration:
"Fix the TouchDesigner executable path to C:\Program Files\Derivative\TouchDesigner.2025\bin\TouchDesigner.exe."
hoot can update configured process fields, add a new process, or delete a process through the same validated server actions used by the dashboard.
Diagnose a display issue:
"Why is the output frozen?"
hoot can inspect process state, logs, GPU usage, and screenshots before suggesting or taking an action.
Run a privileged command:
"Check the detailed network configuration."
hoot asks for confirmation before running a privileged shell or PowerShell command.
turn controls & reliability
A hoot turn — the model's reasoning plus any tool calls it makes — runs on the server, decoupled from your browser connection. A turn keeps running, and its results still land in the chat, even if your connection drops, you close the tab, or you reload the page mid-turn. When you come back, the dashboard reattaches to the in-flight turn and streams it live from where it left off. Long-running tools (for example sfc /scannow, DISM, or a multi-minute script) survive the same interruptions.
- stop a turn — the stop control halts the whole turn server-side, not just your local view. The model loop stops and no further tool calls are made.
- cancel a running tool — while a tool call is executing, its card shows a cancel control. Cancelling terminates the work on the machine — for the shell tools (
run_command,run_powershell,execute_script) this kills the process tree within a few seconds — and the tool card resolves to "cancelled by user". When a turn targets more than one machine, a single cancel targets every machine the call fanned out to. - interrupted tool calls self-heal — if a tool's result is lost mid-stream, hoot repairs it into an honest error (or recovers it from the machine's completed-command record) so the conversation always continues. Sending a new message while a tool is still running no longer breaks the chat.
approving privileged (tier-3) actions
Tier-3 tools (shell, file writes, deployments, reboot, shutdown) are governed by a per-site approval setting, controlled by the shield toggle in the hoot header (site admins only):
- approval required (the default) — privileged tool calls pause in the chat for an explicit approve/deny before they run.
- approval off — privileged tool calls run immediately with no prompt. Disabling the gate weakens safety, so the toggle asks for confirmation first. It also re-enables the lower-latency local hoot path on the public conversations API; the dashboard chat always runs server-side, gate or no gate.
The setting is stored per site at sites/{siteId}/settings/cortex.requireTier3Approval.
an approval belongs to the turn that asked for it
An approval card says what that turn resolved to, and approving runs the call on exactly those machines — not on whatever the picker shows when you come back to the chat. Ticking more machines in the meantime never widens an approval that is already waiting.
A turn aimed at chosen machines names them (on kiosk-01 and kiosk-02, or on 7 machines: … past a handful). A turn aimed at all machines says so instead — on every machine in this site (7 reachable) — because a chosen seven and a whole site otherwise read identically on the one prompt where the difference matters. The count is the machines the turn can actually reach: offline machines and machines with hoot off are already excluded.
If another turn has run in the conversation since the approval was requested — a scheduled follow-up firing, or a message sent from another device — the approval no longer matches the turn it belongs to, and it is refused: that approval expired — another turn ran in this chat. ask again. Nothing is queued on any machine and the approval is not spent; the conversation reloads and the request can be made again.
The bound machines are re-checked when you answer. One that went offline, or had hoot switched off while the card waited, is dropped from the call. If none of them is reachable, the approval is left unanswered rather than consumed, so it can still be approved once a machine comes back.
sharing a conversation
A conversation you started can be published as a read-only web page. The share conversation control in the chat header opens a dialog that previews the finished page, then creates a link to it at /share/{token}.
A share is a snapshot, not a live view. It is frozen at the moment the link is created, so messages you send afterwards never appear in a link that already exists — to publish more of a conversation, create a new link.
what a reader sees
Published:
- your messages and hoot's replies, as text
- the conversation title, and the machines the chat targeted — one name, a list such as kiosk-01, kiosk-02 +3, or All Machines for a site-wide chat
- each tool call, collapsed to the tool's name and how it ended — completed, failed, denied, or not completed
Never published:
- what a tool was asked and what it answered — hostnames, paths, log lines, command output, file contents
- image attachments and screenshots
- system messages, the model's reasoning, and every other internal part of a turn
the preview is the page
hoot's replies are published exactly as written, so a machine name, a file path, or a log line the model quoted in its answer goes out with the share. The dialog renders the finished page before anything is created — read it, then create the link.
links, expiry, and revoking
Anyone holding the link can read the page — there is no sign-in. Treat the link itself as the secret: it is unguessable and is never listed anywhere, but nothing beyond the link gates the page. The page is marked noindex, so search engines do not list it.
A link expires 30 days after it is created by default. The dialog also offers 7 days, 90 days, and never (until revoked).
Every link you have created for a conversation is listed in the same dialog under active links, each with a revoke control. Revoking takes effect immediately and cannot be undone: the page starts reporting that the conversation is not available, and sharing again means creating a new link. An expired link behaves identically, and a reader cannot tell a revoked link from an expired one or from a link that never existed.
Autonomous conversations cannot be shared. A share is published by the person who started the conversation, and an autonomous investigation has no author — the share conversation control does not appear on those chats.
tool tiers
Tier 1 tools read machine or site state, such as system info, logs, process lists, disk usage, GPU state, agent health, and site deployment presets.
Tier 2 tools perform bounded management actions with validated parameters, such as restarting configured processes, adding/editing/deleting process config, capturing screenshots, managing selected Windows services or update settings, and changing safe machine configuration.
Tier 3 tools can make broader changes, such as shell execution, file writes, deployment orchestration, reboots, and shutdowns. These are governed by the per-site tier-3 approval setting (on by default): when it is on, they pause for an explicit approve/deny in the hoot UI before running. See approving privileged (tier-3) actions.
See the hoot tools reference for the current tool list and parameter schemas.
how it works
Every dashboard chat runs the same way. POST /api/hoot carries the chat's target as target.machineIds — an explicit list, or null for the dynamic all machines — and the web server resolves it once, before the turn starts: the ids have to belong to this site, and machines that are offline or have hoot off drop out. The turn is then handed that resolved list and can only ever narrow it, never widen it. Which execution path it takes depends on how many machines are left.
one machine
When a turn effectively targets a single machine — one machine ticked, one @mention, or all machines on a site that has exactly one — hoot runs the single-machine path: that machine's configured processes go into the prompt, tool output is reported unwrapped, and the machine's hoot power toggle is in the header. The turn runs detached from your browser connection, so it survives disconnects and reloads:
dashboard chat
  -> POST /api/hoot with target.machineIds
  -> resolve the signed-in user's key
  -> resolve the target: in this site, online, hoot on
  -> web server runs the turn (detached from your connection)
  -> tier-1/2 tool calls are relayed to the agent through Firestore commands
  -> tier-3 calls pause for in-chat approval, then run
  -> agent writes completed-command results
  -> web server feeds results back to the model and streams the answer to the chat
Members always use this path with a read-only tool tier cap.
several machines (fan-out)
When more than one machine survives resolution, the web server fans tool calls out to each of them and aggregates the per-machine results:
dashboard chat
  -> POST /api/hoot with target.machineIds (null = all machines)
  -> web server resolves the set: in this site, online, hoot on
  -> the model is told which machines this turn targets, and which were skipped
  -> web server calls the LLM provider
  -> tools either run server-side or fan out through Firestore commands
  -> per-machine results are aggregated for hoot
Server-side tools such as site logs, system presets, deployment orchestration, and process config changes run in the web server instead of routing through a single agent. Process create/update/delete tools call the existing validated process actions directly; the agent applies the resulting config through its normal Firestore listener.
local hoot (public conversations API only)
There is a third path, where the model loop and tools run on the agent itself, closer to the machine, for lower latency — at the cost of the approval gate and the tier caps, which the web server cannot enforce inside the agent. It is reached only through the public conversations API, for a single-machine conversation, when the caller is a site admin, the site's tier-3 approval gate is off, and local hoot is healthy on that machine:
POST /api/hoot/conversations/{conversationId}
  -> Firestore active-chat pending message
  -> local hoot on the agent runs the LLM and local tools
  -> local hoot writes response updates to Firestore
  -> the caller streams those updates back
The dashboard chat never takes this path — it always runs server-side, so the approval gate and the tier caps hold.
autonomous mode
Autonomous hoot can investigate process crashes or process-start failures without a human starting a chat. It is triggered by the agent alert path, authenticated with CORTEX_INTERNAL_SECRET, and runs against one affected machine.
flow
agent alert
  -> POST /api/agent/alert
  -> internal POST /api/hoot/autonomous with x-cortex-secret
  -> check site autonomous settings
  -> deduplicate by machine/process cooldown and nonce
  -> enforce per-site concurrency
  -> run an LLM investigation with tier-capped tools
  -> store the event and conversation for review
  -> escalate by email when unresolved, offline, or disabled
Autonomous conversations appear in the hoot sidebar with an auto badge. Event records are stored at sites/{siteId}/cortex-events/ with status, summary, tool-call actions, timestamps, and outcomes.
directive
Every autonomous investigation is guided by a directive. The default mission is to keep configured processes running and machines operational, investigate crashes through logs and process status, restart when appropriate, and escalate if repeated restart attempts fail.
Custom directives can be set in Firestore at sites/{siteId}/settings/cortex in the directive field.
enabling autonomous mode
- Set
CORTEX_INTERNAL_SECRETin the web runtime environment. - Make sure the site owner has saved an LLM key in their account settings — that is the key autonomous investigations run on.
- Set
sites/{siteId}/settings/cortex.autonomousEnabledtotrue.
configuration options
| setting | default | description |
|---|---|---|
autonomousEnabled | false | Master switch for autonomous investigations |
directive | Default directive | Site-specific mission text for autonomous hoot |
maxTier | 2 | Maximum tool tier for autonomous investigations |
cooldownMinutes | 15 | Deduplication window for the same machine and process |
escalationEmail | true | Sends escalation email when hoot cannot resolve the issue |
guardrails
- Autonomous mode is opt-in per site.
- Events are deduplicated by machine and process for the configured cooldown window.
- Duplicate nonces are rejected.
- Each site can run only a limited number of active autonomous sessions at once.
- Each investigation has a fixed step limit.
- The default tier cap prevents shell commands unless the site explicitly raises
maxTier. - The per-machine hoot toggle blocks tool execution for that machine on every path: single-machine chats, multi-machine fan-out, scheduled follow-ups, talons, autonomous investigations, and the public conversations API.
- Offline machines escalate instead of consuming LLM calls.
security
- LLM keys are encrypted at rest and resolved only on the server.
- Every key belongs to one person. Chat spends the signed-in user's key; a talon spends its creator's, re-checked against site access on every run; autonomous mode spends the site owner's.
- Tier 3 tools are governed by the per-site approval setting (on by default): when on, they require an explicit in-chat approve/deny before running.
- An approval is bound to the turn that requested it and runs only on that turn's machines. An approval that a later turn has made stale is refused, never re-aimed at a target nobody reviewed.
- The machines a turn may reach are resolved on the server from ids that must belong to the verified site; a request can only narrow that set, never widen it, and an unreadable stored target sends nothing at all.
- Server-side hoot checks site access before every chat request, and sending, stopping, or cancelling a turn verifies the caller owns the target conversation.
- Members and chat-scoped API keys are capped to read-only tools, and a follow-up they schedule fires under the same cap.
- Agent-routed tool calls are delivered through Firestore command documents and return through completed-command records. Server-side tools run in the web process and write their own records or config changes.
- The autonomous endpoint uses
x-cortex-secretand is not a public user-session endpoint.
swoop
swoop is the dashboard's remote desktop: a live, interactive view of a machine's screen, with keyboard and mouse control behind a second factor. it is off until a site turns it on, every session is leased and audited, and an API key can never start one.
talons
talons are site-scoped automations: a trigger, an optional condition, and one or more outputs. hoot can create them conversationally, and every run is recorded.